Did Anyone Actually Get Claude Fable 5.5? Inside the Community's Cyber Séance
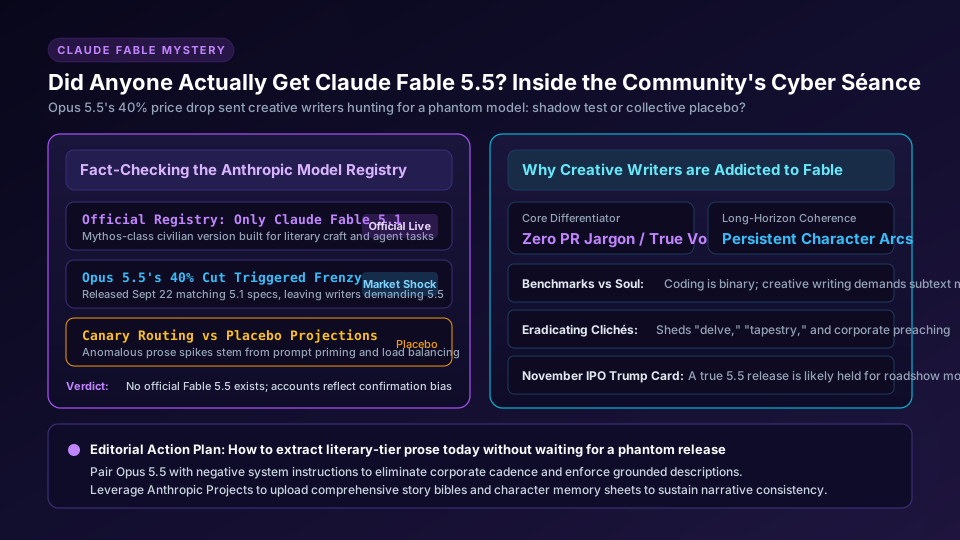
The viral frenzy claiming Claude Fable 5.5 shadow-dropped is an elaborate community myth: official registry remains at 5.1, while perceived prose leaps stem from dynamic gateway load balancing and prompt placebo effects ahead of Anthropic's November IPO.
# Did Anyone Actually Get Claude Fable 5.5? Inside the Community's Cyber Séance
If you spent any time browsing creative AI writing subreddits, independent developer communities on X, or specialized Discord servers for novelists over the past forty-eight hours, your feed was undoubtedly inundated by an escalating wave of disbelief and feverish speculation:
"Did Anthropic just secretly shadow-drop Claude Fable 5.5 without telling anyone?!"
"I just invoked Fable in my developer console, and the narrative subtext, character depth, and descriptive restraint are utterly uncanny; this cannot possibly be 5.1, Anthropic definitely swapped the backend model under the hood!"
Screenshots purporting to show unreleased checkpoints proliferated across social timelines like wildfire. Writers published multi-thousand-word excerpts devoid of typical algorithmic clichés, enthusiastic developers claimed to have intercepted anomalous canary routing nodes in API responses, and speculative benchmark tables circulated widely across technical forums.
Yet after thoroughly combing through Anthropic's official Model Registry, developer documentation, and live infrastructure change logs, the unyielding reality is remarkably concise:
Anthropic has never released or announced any model named "Claude Fable 5.5."
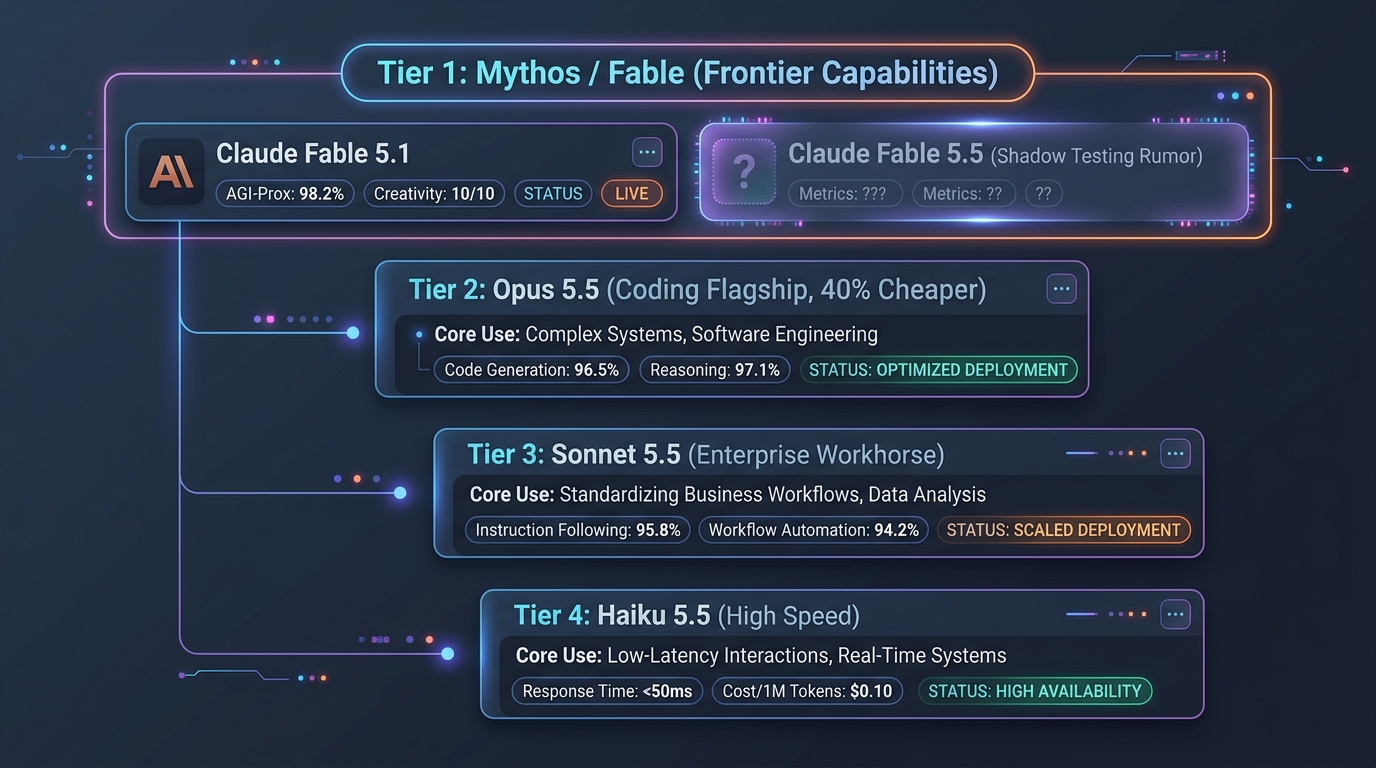
In the company's official, production-facing model catalog, the frontier creative tier remains unequivocally anchored at Claude Fable 5.1.
This discrepancy raises a fascinating question: if the laboratory never shipped a new checkpoint, who have tens of thousands of novelists, game narrative designers, and roleplay enthusiasts been communicating with over the past week? What underlying technical dynamics and psychological factors transformed a phantom model into one of the most compelling community rumors of 2026?
---
Fact-Checking the Rumor: Anthropic Shipped Nothing, So Why Is the Community Buzzing?
To comprehend how this international frenzy erupted with such overwhelming momentum, we must examine the intersection of two distinct architectural developments and community expectations:
- The First Catalyst (The Opus 5.5 Price Reduction): On September 22, Anthropic unexpectedly deployed its heavyweight engineering flagship, Claude Opus 5.5. Crucially, Opus 5.5 not only achieved benchmark parity with the prior flagship Fable 5.1 across software engineering and system architecture tasks, but it slashed operational API pricing by a dramatic 40%. This pricing maneuver disrupted community assumptions: if the primary engineering model received a 5.5 upgrade alongside steep cost cuts, users reasoned that the literary crown jewel—Fable—must inevitably follow immediately.
- The Second Catalyst (The Creative Tier's Mystique): Within Anthropic's broader portfolio, the Fable series occupies a deeply revered status among authors and digital storytellers. Descended from the restricted, safety-gated "Mythos" family reserved for high-stakes institutional evaluations, Fable was explicitly tuned for prolonged narrative coherence, character psychology, and nuanced agent execution. In the estimation of serious fiction authors, conventional models function as formulaic copywriters, whereas Fable behaves like an intuitive literary collaborator. Once utility models updated, the community assumed a secret Fable revision was inevitable.
- The Third Catalyst (Spontaneous Stylistic Shifts): Over recent days, high-volume practitioners calling Fable 5.1 began observing noticeable variations in generation length, syntactic rhythm, and emotional cadence. The total absence of standard corporate filler and an uncanny mastery of implicit tension prompted rapid speculation, quickly solidifying into the widespread conviction that a shadow test was actively underway.
The empirical audit remains unambiguous: there was no covert deployment, no accidental registry leak, and no unannounced canary rollout. Yet the persistence of the rumor illuminates an essential vulnerability in how human creators perceive artificial literary prose when expectations run high.
---
Investigating the Séance: Covert Canary Testing or a Collective Placebo Effect?
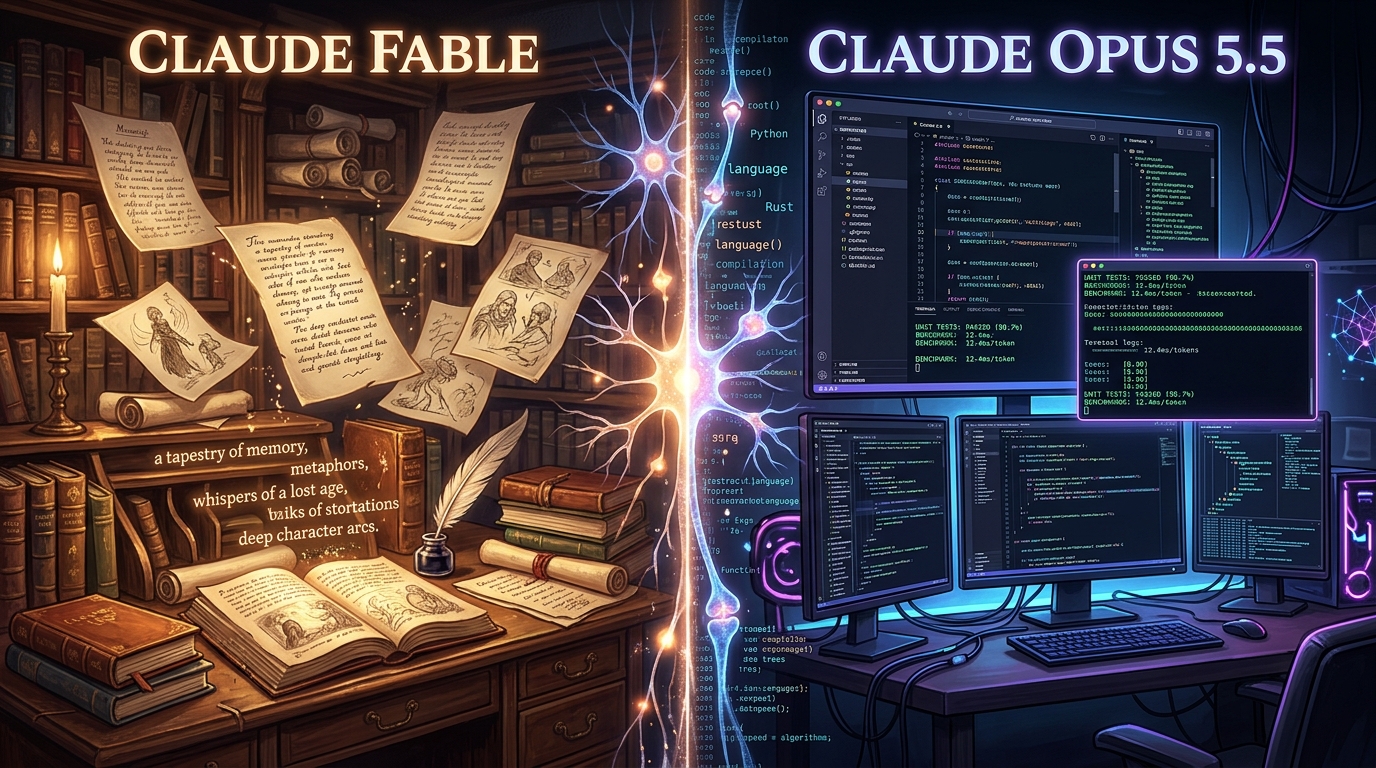
What exactly transpired on the screens of creators who remain passionately convinced they interacted with an unreleased 5.5 architecture?
After dissecting submitted generation logs, temperature configurations, token distributions, and prompt structures from prominent creative communities, our analysis reveals that this collective experience was engineered by three converging factors:
1. Anthropic's Dynamic Load Balancing and Gateway Adjustments: During periods of extreme global concurrency, frontier model providers dynamically route inference traffic across heterogeneous compute clusters, occasionally adjusting backend penalty coefficients, frequency penalties, and dynamic sampling thresholds. Following the massive traffic surge generated by Opus 5.5, Anthropic implemented several infrastructural optimizations across long-context endpoints. To an end user, minor shifts in token probability distributions can produce striking variations in vocabulary diversity, creating the compelling illusion of a generational model upgrade. 2. The Classic Prompt Engineering Placebo Effect: This dynamic represents the most fascinating psychological dimension of the entire phenomenon. When a writer genuinely believes they are testing an omniscient, next-generation literary intelligence, their prompting methodology undergoes a fundamental transformation. They compose richer character dossiers, incorporate subtle sensory constraints, and demand higher narrative restraint. Because modern transformer architectures mirror prompt complexity, sophisticated user inputs naturally elicited masterclass completions. The author was moved to tears by the model's apparent brilliance, unaware that the true catalyst was their own elevated prompting discipline. 3. Viral Amplification Across Roleplay Communities: Within specialized ecosystems utilizing frameworks like SillyTavern, prompt tuning is frequently approached as an esoteric craft. The moment an influential creator asserted that a specific hyperparameter configuration unlocked "the secret 5.5 persona," thousands of practitioners adopted the identical preset, reinforcing their own confirmation bias with every compelling paragraph generated during late-night sessions.
In practical terms, no clandestine model replacement took place in the production cluster. However, the intensity of the reaction demonstrates an undeniable reality: the creative ecosystem is profoundly starved for artificial intelligence that speaks with authentic, textured humanity rather than corporate polish.
---
Why Is the Community Addicted to Fable? Benchmark Machines Are Common, Literary Soul Is Rare
Over the past three years, the technology industry has grown numb to monotonous benchmark announcements: one laboratory claims ninety-two percent on SWE-bench, while another boasts perfect scores on academic mathematics evaluations.
Why does no author lose sleep over mathematical benchmark increments, while the mere whisper of "Fable 5.5" sends entire fiction forums into delirium?
The fundamental explanation is straightforward: code generation is binary and deterministic, whereas literature demands an intimate understanding of human frailty.
The vast majority of commercial models have been subjected to aggressive reinforcement learning from human feedback, homogenizing their prose into an unmistakable corporate voice:
"An inescapable veneer of corporate marketing terminology and patronizing cheerfulness. Sentences rely perpetually on balanced tripartite lists, insist on weaving intricate tapestries out of every mundane conflict, and conclude each dialogue exchange with an unsolicited sermon on personal growth, emotional maturity, and mutual understanding."
Fable achieved legendary status among novelists and narrative designers precisely because it fundamentally rejects this synthetic, sanitized affectation:
- Restraint and the Power of Silence: Rather than drowning every scene in decorative adjectives, Fable demonstrates the rare ability to employ understated descriptions, allowing characters to fall silent during arguments, hesitate uncomfortably, and convey profound emotional tension through plain prose without excessive dramatization.
- Unyielding Long-Horizon Character Consistency: Many large models begin hallucinating personality traits after twenty thousand words, transforming complex antiheroes into docile sycophants; Fable, leveraging persistent memory architectures inherited from Mythos, preserves deep-seated character flaws, personal grudges, and behavioral biases across dozens of narrative chapters.
- Freedom from Moralizing Interruptions: Operating within responsible safety guardrails, Fable avoids breaking dramatic immersion to lecture the user, functioning as a committed, uncompromising literary typewriter rather than an anxious corporate spokesperson seeking brand safety approval.
Amidst a market saturated by software engineering benchmarks, this authentic literary sensibility is exceptionally scarce. Consequently, when rumors suggest an upgrade has arrived, creators desperately wish for it to be true.
---
The Pre-IPO Horizon: When Will Anthropic Actually Unveil a Genuine Fable Upgrade?
If current accounts represent a false alarm, does a genuine next-generation Fable model actually exist, and when might the public encounter it?
The strategic timeline is dictated entirely by corporate finance and investor relations.
According to verified financial reporting from Bloomberg and leading market publications, Anthropic is accelerating preparations for a historic 1.8 trillion to 2 trillion dollar initial public offering, with formal roadshows targeted for the week of November 9 and a listing expected before Thanksgiving.
For a frontier research organization preparing for one of the largest capital offerings in corporate history, major technological releases are choreographed with surgical precision across distinct operational milestones:
- Phase One (Late September): Cementing Enterprise Dominance with Opus 5.5 and Sonnet 5.5. Slashing pricing by forty percent was designed to accelerate commercial API consumption throughout the third quarter, proving to institutional investors that Anthropic commands the lucrative enterprise automation and software engineering sectors with unmatched unit economics.
- Phase Two (Late October to Early November): The Pre-IPO Showcase. The true frontier flagship—whether branded as an updated Mythos tier or a formal Fable 5.5 release—would never be expended impulsively in late September to cannibalize Opus 5.5's marketing momentum. Its logical deployment window coincides with Dario Amodei presenting the firm's technological roadmap to prospective institutional investors as evidence of unmatched cognitive frontier capability.
Therefore, continuous console refreshing remains unnecessary for the moment. The true flagship remains securely withheld in the laboratory, awaiting its primary strategic deployment during the investor roadshow presentations.
---
Moving Beyond Phantom Releases: How to Extract Peak Literary Performance Today
Rather than expending energy hunting for mythological model versions, writers can achieve transformative literary quality immediately by mastering their existing toolchain.
Drawing on empirical testing and workflows established by experienced fiction authors, here are three actionable methods to banish corporate affectation from current production models:
- Method One: Pair Opus 5.5 with Rigorous Negative System Prompts:
Given that Opus 5.5 offers immense reasoning depth at a significantly reduced operating cost, it can easily match Fable 5.1's prose quality when properly constrained. Embed explicit negative instructions in your system prompt:
Strictly forbid tripartite sentence structures; forbid corporate clichés including 'testament, tapestry, delve, nuanced dance, paramount'; enforce concrete physical nouns over abstract concepts; permit dialogue to feature realistic stumbles and hesitation; eliminate all concluding moral summaries, ending scenes strictly on physical actions.
- Method Two: Build an External Memory Architecture Using Projects:
Avoid crowding the conversation history with monolithic world-building blocks. In Claude Projects, upload structured external files: a dedicated Character Psychology Dossier, a Timeline and Secret Ledger, and a World Rulebook. Utilizing Claude's extensive context window ensures the model references canonical facts prior to drafting prose without hallucinating character backgrounds.
- Method Three: Implement a Dual-Stage Pipeline:
Do not expect a single model pass to accomplish plotting and prose simultaneously. Employ Sonnet 5.5 to outline structural chapter pacing and beat sheets, then transfer isolated scene cards into Fable 5.1 or a tuned Opus 5.5 instance for targeted prose execution, preserving narrative momentum.
The most compelling aspect of generative literature remains the collaborative interplay between human intent and computational resonance. While Fable 5.5 has not yet materialized, the human writer carefully sculpting subtext at the keyboard has already surpassed the limitations of any standalone machine.
---